Introduction
As application traffic scales, relational databases like PostgreSQL often become the primary bottleneck. While managed platforms like Supabase significantly reduce operational overhead, maintaining sub-10ms query execution during massive concurrent read/write surges requires deliberate architectural design.
In this playbook, we break down the exact strategies we deploy at Isotope Blue to scale Supabase and PostgreSQL backends for enterprise-grade throughput, eliminating lock contention, high CPU utilization, and connection exhaustion.
1. Connection Management & Pooling Strategy
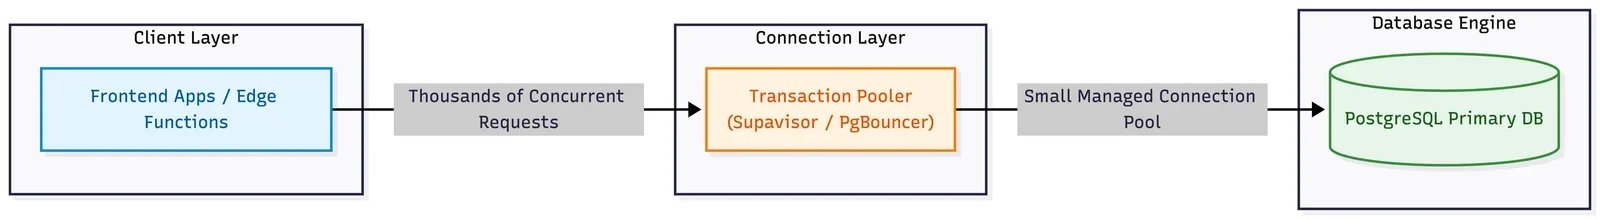
The default PostgreSQL process model assigns a separate backend process to each incoming connection, creating significant memory overhead. Under sudden spikes in traffic, raw connections can quickly exhaust system resources.
The Architecture Solution:
- Transaction-Level Pooling via Supavisor / PgBouncer: Configure poolers in Transaction Mode rather than Session Mode. This allows thousands of client applications to share a significantly smaller pool of active server connections, cutting memory usage by up to 80%.
- Direct Connections for Long-Lived Tasks: Reserve direct PostgreSQL connections strictly for administrative tasks, schema migrations, or continuous real-time listeners, directing all application HTTP requests and API edge functions through the transaction pooler.
2. Query Optimization & Indexing Hygiene
Slow-running queries consume database connections, hold locks, and pin CPU usage. High-throughput performance requires eliminating sequential table scans entirely.
Execution Tactics:
- Partial & Composite Indexes: Avoid indexing every column. Build composite indexes targeted at specific multi-column
WHEREandORDER BYclauses, and use partial indexes (WHERE active = true) to keep index sizes small and cached in RAM. - Covering Indexes (
INCLUDEClause): Include frequently selected payload fields inside the index itself to enable Index Only Scans, allowing PostgreSQL to fulfill queries directly from the index without reading table pages from disk. - EXPLAIN ANALYZE Monitoring: Continuously audit long-running queries to identify missing indexes, high buffer hits, and unexpected sequential scans.
3. Mitigating Write Contention & Lock Overhead
High-volume write operations—such as telemetry logging, click tracking, or real-time state updates—can easily lock rows and degrade read performance across the entire database.
Architectural Patterns:
- Write Buffering via Redis or Queue Workers: Instead of writing every micro-event directly to PostgreSQL, buffer high-frequency writes in an in-memory store (Redis) or queue system (n8n / Kafka), then commit them to PostgreSQL in optimized batch transactions.
- Unlogged Tables for Ephemeral Data: For transient session state or staging data where instant persistence across server crashes isn’t critical, utilize PostgreSQL
UNLOGGEDtables to bypass Write-Ahead Logging (WAL) write overhead.
4. Row-Level Security (RLS) Performance Tuning
Supabase relies heavily on Row-Level Security (RLS) for authorization. However, poorly structured RLS policies can force PostgreSQL to re-evaluate complex expressions or nested queries for every single row returned.
Optimization Rules:
- Always Index Foreign Keys in RLS Policies: Ensure any column referenced inside an RLS policy (e.g.,
organization_id,user_id) is explicitly indexed. - Avoid Correlated Subqueries in Policies: Wrap helper functions in
STABLEorIMMUTABLESQL functions, or use JWT claim checks directly (auth.jwt() -> 'app_metadata' ->> 'org_id') to eliminate subqueries during policy evaluation.
5. Read Replicas & Connection Routing
For read-heavy platforms (e.g., global marketplaces, analytics dashboards), offload SELECT queries entirely from the primary write node.
Deployment Setup:
Asynchronous Read Replicas: Provision read replicas across target geographic regions to serve local read requests with minimum latency.
Read/Write Splitting: Route write operations (INSERT, UPDATE, DELETE) to the primary pooler, while directing complex reporting queries and read requests to replica endpoints.
Unify Your Voice Architecture Today
Integrating Voice AI into legacy setups doesn’t require tearing down your existing infrastructure. By treating voice processing as a streaming engineering challenge rather than a batch script, you can deploy natural, sub-second AI phone agents directly into your existing operations.
Solutions: