Executive Summary
Deploying Large Language Models (LLMs) into customer-facing support roles presents a major operational risk: hallucinations. When a support bot invents a non-existent refund policy or gives incorrect technical instructions, it destroys customer trust and creates legal liabilities.
Standard out-of-the-box LLM prompts cannot reliably prevent hallucinations. Achieving enterprise-grade accuracy requires a guarded Retrieval-Augmented Generation (RAG) architecture. This playbook outlines the exact system design, vector retrieval strategies, and guardrail logic we use at Isotope Blue to build customer support AI agents with near-zero hallucination rates.
1. The Core Architecture Blueprint
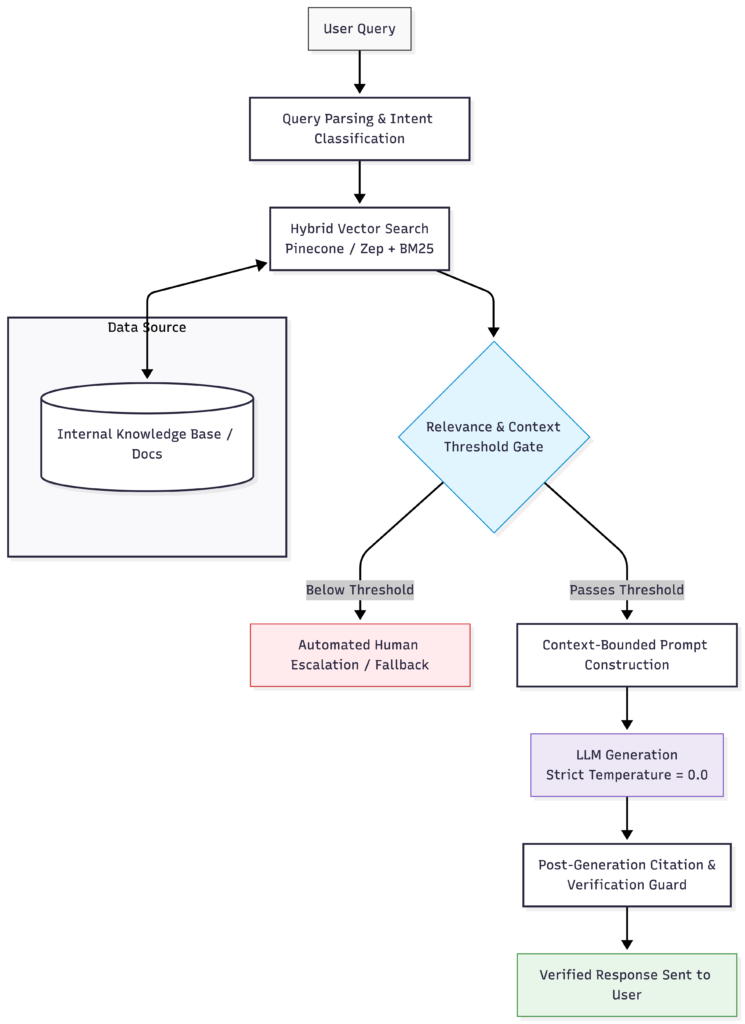
A reliable support RAG pipeline separates knowledge retrieval from language generation. The LLM is never allowed to answer from its pre-trained memory; it acts strictly as a synthesis engine operating on retrieved, verified context.
2. Key Engineering Pillars for Zero Hallucinations
Pillar A: Hybrid Retrieval (Dense Vector + Sparse Keyword Search)
Pure semantic vector search often misses exact technical identifiers, model numbers, or specific error codes. We implement a Hybrid Retrieval Engine:
- Dense Retrieval: Uses vector embeddings (via Pinecone or Zep) to capture conversational intent and conceptual similarity.
- Sparse Retrieval: Uses traditional BM25 keyword matching to ensure exact-match precision for code snippets, SKU numbers, and policy names.
- Reciprocal Rank Fusion (RRF): Merges dense and sparse search results into a single re-ranked context payload before passing it to the prompt.
Pillar B: Rigid Context Boundaries & Fallback Thresholds
The primary cause of hallucination is forcing an LLM to generate an answer when the underlying context does not exist in the knowledge base.
- Relevance Scoring Gate: Every retrieved document chunk receives a cosine similarity/distance score. If no chunk scores above the defined confidence threshold (e.g., $0.82$), the query bypasses generation entirely.
- Deterministic Fallbacks: When context is insufficient, the pipeline executes an automated fallback: “I do not have enough verified information to answer this request accurately. Connecting you to a support specialist…”
Pillar C: Strict System Prompting & Temperature Calibration
We configure the generation layer to act purely as a translator of verified facts:
- Temperature Setting: Forced to $0.0$ to eliminate token randomness and creative drift.
- Strict Negative Constraints: System instructions explicitly forbid assuming external facts or referencing information outside the provided
<context></context>block.
Pillar D: Post-Generation Groundedness Verification
Before the generated response reaches the user, it passes through an automated validation guard:
- Citation Matching: The system checks if every assertion in the output maps back to a specific sentence in the retrieved context block.
- Self-Consistency Verification: A lightweight secondary model evaluates whether the generated output logically contradicts the source document. If a contradiction is detected, the message is intercepted and flagged for human review.
3. Technology Stack Recommendation
| Pipeline Component | Recommended Stack |
| Vector Database | Pinecone (Serverless) or Zep (for dynamic memory + hybrid search) |
| Embedding Models | OpenAI text-embedding-3-large or Cohere Embed v3 |
| Orchestration & Workflow | Python (FastAPI), n8n, or LangChain / LlamaIndex |
| LLM Execution | Claude 3.5 Sonnet / GPT-4o (configured with low temperature) |
| Database Sync | Webhook triggers from Zendesk, Notion, or custom PostgreSQL bases |
4. Key Performance Indicators (KPIs)
When deployed in production, a successful zero-hallucination support engine should deliver the following metrics:
- Hallucination Rate: $< 0.1\%$ across all customer interactions.
- Automated Deflection Rate: $60\% – 80\%$ of tier-1 support tickets resolved without human intervention.
- Sub-Second Latency: Total retrieval and generation pipeline response time under $1.2$ seconds.
- Escalation Precision: $100\%$ accurate routing of unresolved edge cases directly to human support teams with complete conversation transcripts.
Unify Your Support Architecture
Stop relying on generic AI wrappers that put your brand’s reputation at risk. At Isotope Blue, we engineer custom, zero-hallucination AI support infrastructures integrated directly into your existing databases and ticketing systems.
Solutions: